mirror of
https://github.com/openai/codex.git
synced 2026-11-13 14:46:14 +00:00
[codex] request desktop attestation from app (#20619)
## Summary TL;DR: teaches `codex-rs` / app-server to request a desktop-provided attestation token and attach it as `x-oai-attestation` on the scoped ChatGPT Codex request paths. 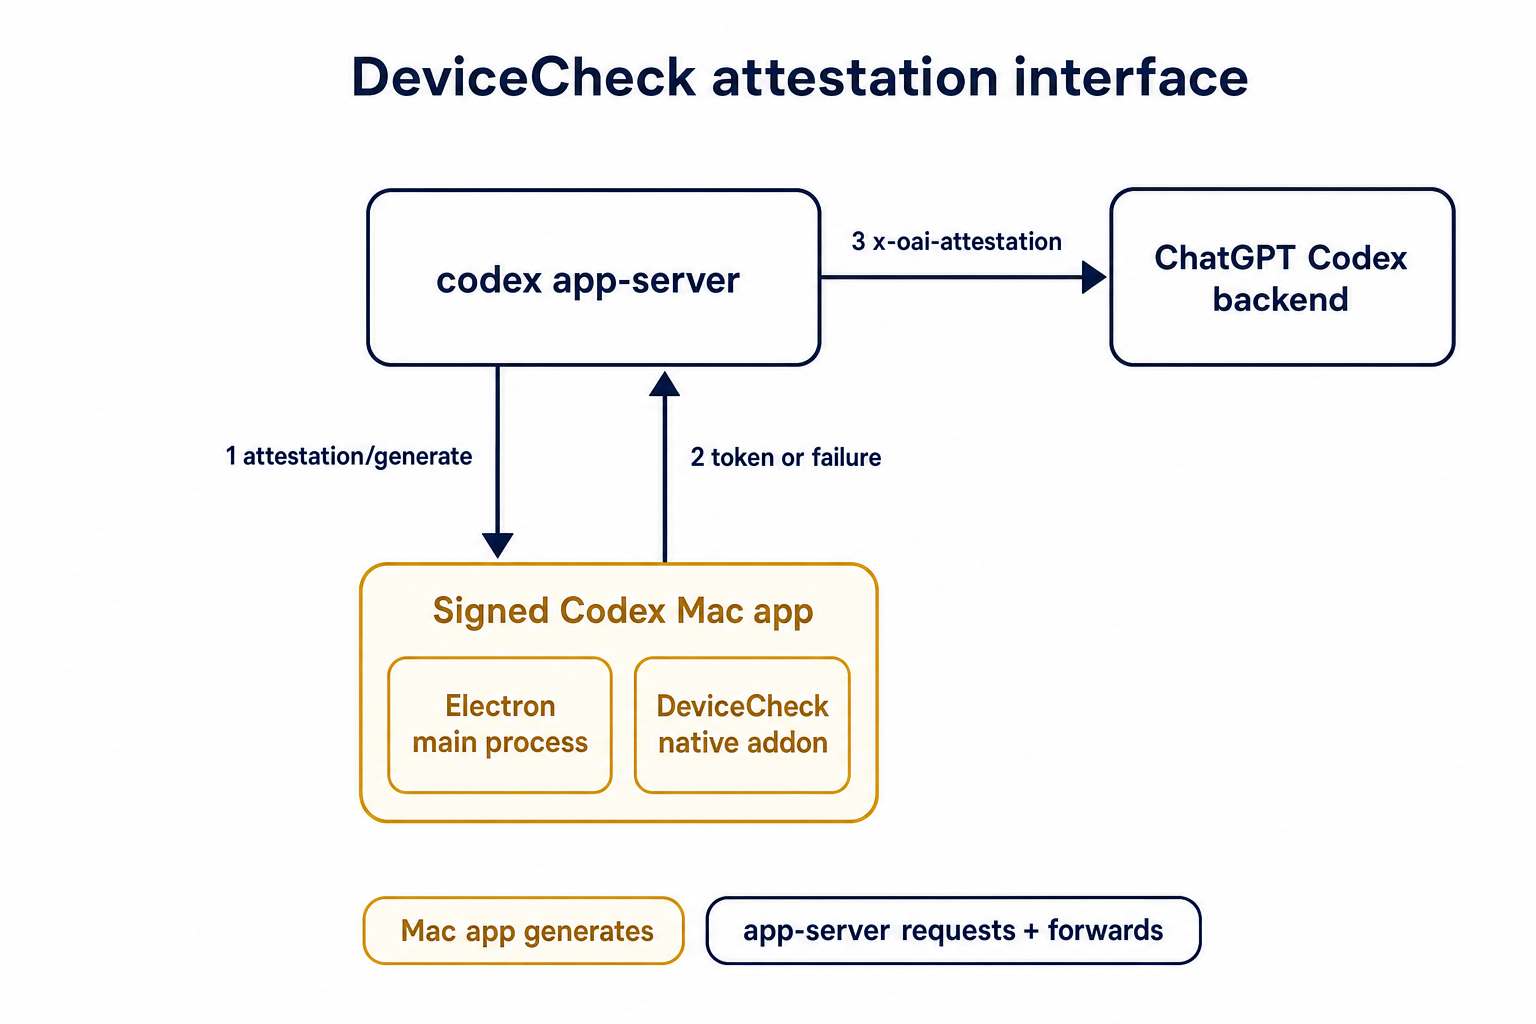 ## Details This PR teaches the Codex app-server runtime how to request and attach an attestation token. It does not generate DeviceCheck tokens directly; instead, it relies on the connected desktop app to advertise that it can generate attestation and then asks that app for a fresh header value when needed. The flow is: 1. The Codex desktop app connects to app-server. 2. During `initialize`, the app can advertise that it supports `requestAttestation`. 3. Before app-server calls selected ChatGPT Codex endpoints, it sends the internal server request `attestation/generate` to the app. 4. app-server receives a pre-encoded header value back. 5. app-server forwards that value as `x-oai-attestation` on the scoped outbound requests. The code in this repo is mostly protocol and runtime plumbing: it adds the app-server request/response shape, introduces an attestation provider in core, wires that provider into Responses / compaction / realtime setup paths, and covers the intended scoping with tests. The signed macOS DeviceCheck generation remains owned by the desktop app PR. ## Related PR - Codex desktop app implementation: https://github.com/openai/openai/pull/878649 ## Validation <details> <summary>Tests run</summary> ```sh cargo test -p codex-app-server-protocol cargo test -p codex-core attestation --lib cargo test -p codex-app-server --lib attestation ``` Also ran: ```sh just fix -p codex-core just fix -p codex-app-server just fix -p codex-app-server-protocol just fmt just write-app-server-schema ``` </details> <details> <summary>E2E DeviceCheck validation</summary> First validated the signed desktop app boundary directly: launched a packaged signed `Codex.app`, sent `attestation/generate`, decoded the returned `v1.` attestation header, and validated the extracted DeviceCheck token with `personal/jm/verify_devicecheck_token.py` using bundle ID `com.openai.codex`. Apple returned `status_code: 200` and `is_ok: true`. Then ran the fuller app + app-server flow. The packaged `Codex.app` launched a current-branch app-server via `CODEX_CLI_PATH`, and a local MITM proxy intercepted outbound `chatgpt.com` traffic. The app-server requested `attestation/generate` from the real Electron app process, and the intercepted `/backend-api/codex/responses` traffic included `x-oai-attestation` on both routes: ```text GET /backend-api/codex/responses Upgrade: websocket x-oai-attestation: present POST /backend-api/codex/responses Upgrade: none x-oai-attestation: present ``` The captured header decoded to a DeviceCheck token that also validated with Apple for `com.openai.codex` (`status_code: 200`, `is_ok: true`, team `2DC432GLL2`). </details> --------- Co-authored-by: Codex <noreply@openai.com>

This commit is contained in:
 Jiaming ZhangandCodex authored and GitHub committed
1 parent
61142b6169
commit
5f4d0ec343
65 files changed
+1086
-39
No files matched your search
@@ -7,13 +7,21 @@ use super::X_CODEX_PARENT_THREAD_ID_HEADER;
|
||||
use super::X_CODEX_TURN_METADATA_HEADER;
|
||||
use super::X_CODEX_WINDOW_ID_HEADER;
|
||||
use super::X_OPENAI_SUBAGENT_HEADER;
|
||||
use crate::AttestationContext;
|
||||
use crate::AttestationProvider;
|
||||
use crate::GenerateAttestationFuture;
|
||||
use codex_api::ApiError;
|
||||
use codex_api::ResponseEvent;
|
||||
use codex_app_server_protocol::AuthMode;
|
||||
use codex_login::AuthManager;
|
||||
use codex_login::CodexAuth;
|
||||
use codex_model_provider::BearerAuthProvider;
|
||||
use codex_model_provider_info::CHATGPT_CODEX_BASE_URL;
|
||||
use codex_model_provider_info::ModelProviderInfo;
|
||||
use codex_model_provider_info::WireApi;
|
||||
use codex_model_provider_info::create_oss_provider_with_base_url;
|
||||
use codex_otel::SessionTelemetry;
|
||||
use codex_protocol::SessionId;
|
||||
use codex_protocol::ThreadId;
|
||||
use codex_protocol::models::ContentItem;
|
||||
use codex_protocol::models::ResponseItem;
|
||||
@@ -36,6 +44,8 @@ use std::collections::VecDeque;
|
||||
use std::pin::Pin;
|
||||
use std::sync::Arc;
|
||||
use std::sync::Mutex;
|
||||
use std::sync::atomic::AtomicUsize;
|
||||
use std::sync::atomic::Ordering;
|
||||
use std::task::Context;
|
||||
use std::task::Poll;
|
||||
use std::time::Duration;
|
||||
@@ -64,6 +74,7 @@ fn test_model_client(session_source: SessionSource) -> ModelClient {
|
||||
/*enable_request_compression*/ false,
|
||||
/*include_timing_metrics*/ false,
|
||||
/*beta_features_header*/ None,
|
||||
/*attestation_provider*/ None,
|
||||
)
|
||||
}
|
||||
|
||||
@@ -466,3 +477,107 @@ fn auth_request_telemetry_context_tracks_attached_auth_and_retry_phase() {
|
||||
assert_eq!(auth_context.recovery_mode, Some("managed"));
|
||||
assert_eq!(auth_context.recovery_phase, Some("refresh_token"));
|
||||
}
|
||||
|
||||
fn model_client_with_counting_attestation(
|
||||
include_attestation: bool,
|
||||
) -> (ModelClient, Arc<AtomicUsize>) {
|
||||
#[derive(Debug)]
|
||||
struct CountingAttestationProvider {
|
||||
calls: Arc<AtomicUsize>,
|
||||
}
|
||||
|
||||
impl AttestationProvider for CountingAttestationProvider {
|
||||
fn header_for_request(
|
||||
&self,
|
||||
_context: AttestationContext,
|
||||
) -> GenerateAttestationFuture<'_> {
|
||||
let calls = self.calls.clone();
|
||||
Box::pin(async move {
|
||||
let call = calls.fetch_add(1, Ordering::Relaxed) + 1;
|
||||
Some(http::HeaderValue::from_bytes(format!("v1.header-{call}").as_bytes()).unwrap())
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
let attestation_calls = Arc::new(AtomicUsize::new(0));
|
||||
let (auth_manager, provider) = if include_attestation {
|
||||
(
|
||||
Some(AuthManager::from_auth_for_testing(
|
||||
CodexAuth::create_dummy_chatgpt_auth_for_testing(),
|
||||
)),
|
||||
ModelProviderInfo::create_openai_provider(Some(CHATGPT_CODEX_BASE_URL.to_string())),
|
||||
)
|
||||
} else {
|
||||
(
|
||||
None,
|
||||
create_oss_provider_with_base_url("https://example.com/v1", WireApi::Responses),
|
||||
)
|
||||
};
|
||||
let model_client = ModelClient::new(
|
||||
auth_manager,
|
||||
SessionId::new(),
|
||||
ThreadId::new(),
|
||||
/*installation_id*/ "11111111-1111-4111-8111-111111111111".to_string(),
|
||||
provider,
|
||||
SessionSource::Exec,
|
||||
/*model_verbosity*/ None,
|
||||
/*enable_request_compression*/ false,
|
||||
/*include_timing_metrics*/ false,
|
||||
/*beta_features_header*/ None,
|
||||
Some(Arc::new(CountingAttestationProvider {
|
||||
calls: attestation_calls.clone(),
|
||||
})),
|
||||
);
|
||||
(model_client, attestation_calls)
|
||||
}
|
||||
|
||||
#[tokio::test]
|
||||
async fn websocket_handshake_includes_attestation_for_chatgpt_codex_responses() {
|
||||
let (model_client, attestation_calls) =
|
||||
model_client_with_counting_attestation(/*include_attestation*/ true);
|
||||
|
||||
let headers = model_client
|
||||
.build_websocket_headers(/*turn_state*/ None, /*turn_metadata_header*/ None)
|
||||
.await;
|
||||
|
||||
assert_eq!(
|
||||
headers
|
||||
.get(crate::attestation::X_OAI_ATTESTATION_HEADER)
|
||||
.and_then(|value| value.to_str().ok()),
|
||||
Some("v1.header-1"),
|
||||
);
|
||||
assert_eq!(attestation_calls.load(Ordering::Relaxed), 1);
|
||||
}
|
||||
|
||||
#[tokio::test]
|
||||
async fn non_chatgpt_codex_endpoints_omit_attestation_generation() {
|
||||
let (model_client, attestation_calls) =
|
||||
model_client_with_counting_attestation(/*include_attestation*/ false);
|
||||
let mut response_headers = http::HeaderMap::new();
|
||||
|
||||
if let Some(header_value) = model_client.generate_attestation_header_for().await {
|
||||
response_headers.insert(crate::attestation::X_OAI_ATTESTATION_HEADER, header_value);
|
||||
}
|
||||
let mut compaction_headers = http::HeaderMap::new();
|
||||
if let Some(header_value) = model_client.generate_attestation_header_for().await {
|
||||
compaction_headers.insert(crate::attestation::X_OAI_ATTESTATION_HEADER, header_value);
|
||||
}
|
||||
let mut realtime_headers = http::HeaderMap::new();
|
||||
if let Some(header_value) = model_client.generate_attestation_header_for().await {
|
||||
realtime_headers.insert(crate::attestation::X_OAI_ATTESTATION_HEADER, header_value);
|
||||
}
|
||||
|
||||
assert_eq!(
|
||||
response_headers.get(crate::attestation::X_OAI_ATTESTATION_HEADER),
|
||||
None,
|
||||
);
|
||||
assert_eq!(
|
||||
compaction_headers.get(crate::attestation::X_OAI_ATTESTATION_HEADER),
|
||||
None,
|
||||
);
|
||||
assert_eq!(
|
||||
realtime_headers.get(crate::attestation::X_OAI_ATTESTATION_HEADER),
|
||||
None,
|
||||
);
|
||||
assert_eq!(attestation_calls.load(Ordering::Relaxed), 0);
|
||||
}
|
||||
Reference in new issue
Block a user